
AI Ethics
The Ethics of Agentic AI: Who Is Responsible When an Agent Makes a Mistake?
Short answer
Responsibility for an agent’s mistake is currently shared between whoever set its goal, whoever built it, the model provider and the organisation that deployed it — which is why governance has to be settled in advance: narrow permissions, human checkpoints before irreversible actions, full audit trails, and escalation instead of improvisation.
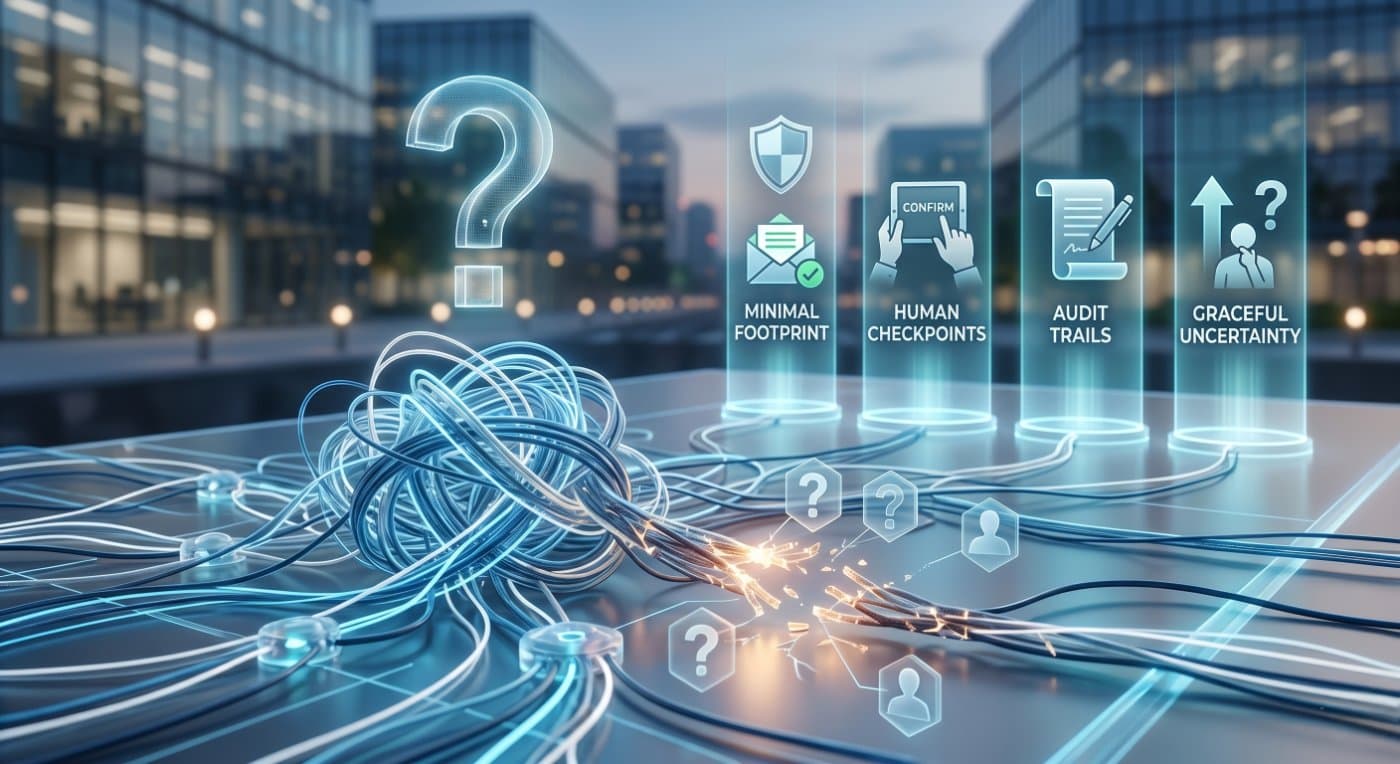
When an agent gets it wrong, who is at fault?
When an employee makes a costly mistake, the lines are reasonably clear. There is a person, a decision, a manager, a process that failed. When an agent acting on its own — making dozens of decisions nobody reviewed — causes the same harm, those lines dissolve.
The reason is autonomy. Ordinary AI is reactive: a person chooses to use it, reads the output and decides what to do with it. The human stays the decision-maker, and responsibility stays where it always was. An agent given a goal takes hundreds of actions before anyone looks — browsing, writing code, sending messages, spending money, changing files. The chain from instruction to outcome is long, and frequently nobody can reconstruct it afterwards.
This is not a philosophy-seminar problem. Agents are moving into ordinary business infrastructure now, and the question of who answers for them is practical, pressing and substantially unresolved. Anyone deploying one is taking a position on it, whether they have thought about it or not.
The four candidates
When an agentic system causes harm, responsibility could reasonably land on any of four parties:
- The user who set the goal and configured the agent — including the permissions it was given and the checkpoints it was not.
- The developer who built it and chose its tools, its constraints and its behaviour on encountering the unexpected.
- The AI company whose model does the reasoning, and whose failure modes are inherited by everything built on it.
- The organisation that deployed it, profited from it, and decided how much supervision to pay for.
Under most current legal frameworks the answer is some combination of all four, apportioned after the fact by people with limited enthusiasm for the technical detail. There is very little precedent, which means the practical risk today is not being unfairly blamed — it is discovering that nobody decided in advance who was accountable, and that the logs needed to work it out were never kept.
Four principles that actually hold up
These are not aspirational. They are what separates a deployment you can defend from one you cannot:
- Minimal footprint. An agent gets only the permissions its task requires, and nothing more. An agent that reads email does not get permission to send email unless sending is genuinely part of the job. Most permission sprawl happens because it was convenient during building.
- Human checkpoints. High-stakes or irreversible actions require confirmation before execution. Sending to five thousand customers, issuing a refund, deleting anything, committing money — these should stop and ask, every time.
- Audit trails. Every action logged, with the reason it was taken. This is unglamorous and it is the difference between an incident you can explain in an afternoon and one you cannot explain at all. It is also how you debug, which is why it pays for itself long before you need it for accountability.
- Graceful uncertainty. When the agent meets something outside its expected scope, it should stop and escalate rather than improvise. Improvisation is where the expensive surprises live, and a model's willingness to have a go is a liability at exactly this moment.
Deploying an agent with no governance — undefined permissions, no audit trail, no checkpoints, no named owner — is running a business without insurance. It is fine until it is not, and then it is very much not.
Corrigibility, sandboxing and oversight
Three engineering practices carry most of the weight. None of them is exotic.
Corrigibility is the property of being correctable: a system that can be adjusted, interrupted or shut down by a person, and that does not resist it. In practice this means flagging uncertainty instead of pushing through, escalating edge cases, and being updatable or reversible without breaking everything downstream. For an agent it matters more than for anything else, because an agent that cannot be stopped mid-task is a standing liability — and mid-task is precisely when you will want to stop it.
Sandboxing limits the blast radius. The support agent has no route to the financial systems. Code runs in an isolated environment that cannot touch production. This does not prevent mistakes — nothing prevents mistakes — it decides how far one mistake can travel. Most catastrophes are an ordinary error in an environment that allowed it to spread.
Human oversight is the part people either skip or overdo. It does not mean reviewing every output, which would remove the point of automation. It means checkpoints in sensible places: review before consequential actions, a clear escalation path when the agent is unsure, and periodic audits of what it has actually been doing in production — as opposed to what you assumed it was doing.
And transparency underneath all of it. When a decision affects someone's job, money or rights, there has to be an account of how it was reached. "The model said so" is not accountability. If a system's reasoning cannot be traced and explained, it should not be making that class of decision. Safety is not the opponent of capability here: the systems trusted at the largest scale are also the most carefully constrained.
Bias is arithmetic, not opinion
Bias is the most misunderstood item on this list. Some people dismiss it as a political talking point; others conclude AI is untrustworthy in general. Both are wrong, and the mechanism is mathematical rather than ideological.
A model learns from data. Where that data carries historical inequality, the model learns the inequality as a pattern and reproduces it — often amplifying it, because it has no notion that the pattern was unjust rather than predictive. No intent is required and none is present.
It enters in three ways. Training data: a hiring model trained on decades of records from an industry that favoured men learns that being male correlates with being hired, and discriminates accordingly even when gender is nowhere in its inputs — Amazon abandoned a recruiting tool for precisely this. Representation: facial recognition trained mostly on light-skinned faces performs markedly worse on dark-skinned ones; medical models trained on data from wealthy health systems perform poorly where disease patterns and diagnostic equipment differ. Measurement: the proxy itself can be loaded — recidivism scores used in parole decisions inherit racial bias from policing and prosecution patterns, so the arithmetic is clean and the conclusion is still unjust.
Eliminating it entirely is probably not possible. Reducing it substantially is ordinary engineering discipline: audit the training data for representation gaps, test across demographic groups before deployment rather than after the complaint, get more than one kind of person into the design, use the detection tooling that exists, and monitor in production for drift. AI does not invent bias. It reflects and magnifies what is already in the data and the institutions that produced it, which means addressing it is partly a technical problem and partly not.
Will it take your job? The honest answer
The most rigorous economic work on this points to one consistent finding: AI automates tasks, not jobs. Almost every job is a bundle of tasks, some highly routine and easy to automate, others requiring judgement, physical dexterity, social intelligence or context that these systems handle badly. What happens in practice is that the automatable tasks go, and the job changes shape rather than disappearing.
Goldman Sachs estimated in 2023 that AI could automate work equivalent to 300 million full-time jobs globally — and noted in the same report that previous technological shifts created more employment than they destroyed, frequently in sectors that did not exist beforehand. The internet eliminated millions of jobs and created many more. That is a reason for seriousness, not comfort: the aggregate being fine is small consolation to a particular person in a particular year.
Highest exposure: routine, well-defined work; heavy information processing, document analysis and data entry; little physical manipulation of unpredictable environments; little need for genuine human connection. That covers a great deal of clerical and administrative work, and the repetitive portions of law, accounting and radiology. Most resilient: complex physical work in unpredictable settings — plumbers, electricians, surgeons; fundamentally relational work — teachers, nurses, therapists; creative judgement in genuinely novel situations; and the work of directing AI systems and evaluating whether they did the job.
The genuinely dangerous position is not being in an exposed role. It is being in an exposed role and declining to adapt. A lawyer using these tools for research, drafting and review becomes substantially more valuable; a lawyer refusing to touch them competes against colleagues who did. Same technology, opposite outcomes, decided entirely by the response.
The work that grows instead
Knowledge work shifts from doing toward directing, evaluating and deciding. The lawyer spends less time reading documents and more on strategy and clients; the marketer less time writing copy and more on audience and campaign design; the analyst less time on the numbers and more on what they mean. The human role moves up the chain toward judgement and accountability — which is also where it becomes harder to automate.
Roles that did not meaningfully exist five years ago and are now being hired: people who define what an AI system should do and own its performance; people who design the instructions and interaction patterns that make it useful in a specific domain; people who supply the human feedback that trains model behaviour; people who audit systems for bias, accuracy and compliance, a role that grows with every new regulation; and people who architect multi-agent systems — deciding which agent handles what, how they communicate, and where the human checkpoints sit.
The skills underneath those are four: evaluating AI output critically rather than accepting it; collaborating with these tools well, including knowing when to override them; systems thinking, because once execution is automated the people who understand how tasks fit into processes become disproportionately valuable; and interpersonal leadership, which gets more valuable as the transactional work goes.
The same split applies to organisations. The ones treating this as a way to cut headcount get a short-term saving and a long-term problem. The ones treating it as a capability multiplier — AI literacy across the whole workforce, systematic rather than sporadic experiments, governance built before it is needed — get the opposite.
What people get wrong, in both directions
Fear and hype are both expensive. Fear keeps people away from tools that would help them; hype produces bad decisions and disappointment. The persistent errors, briefly:
- That it thinks, or feels. It does not. It processes patterns and produces statistically likely output. A model that writes a fine poem has no idea what beauty is, and one that says it is happy to help is generating contextually appropriate words, not reporting an inner state.
- That it is usually right. It is confidently wrong on a regular basis — fabricating facts, misreading questions, failing at the edges. Oversight is not optional on anything that matters.
- That it is objective. See the section above. It is not a neutral referee; it is a mirror with a multiplier.
- That it will take all the jobs, or none of them. Both wrong, in the directions described above.
- That you need to be a programmer. You need to write clear instructions, which is a real skill and not a technical one.
- That it is new, or that it is only for large companies. The research goes back to the 1950s; what changed is scale and accessibility. A sole trader and a bank now use the same frontier models.
- That general human-level AI is imminent. It remains an open research problem with no scientific consensus on when, or whether. Anyone confident either way is selling something.
- That nobody is in control. These systems are built, deployed and regulated by people. What data to train on, what safeguards to build, what to permit — all human decisions. The fatalistic framing is both wrong and convenient for anyone who would rather not decide.
What to do before you deploy anything
Write down who is accountable for the agent's actions, by name. Give it the narrowest permissions that let it do the job. Put a checkpoint in front of anything irreversible or expensive. Log everything it does and actually read the log in the first weeks. Decide what it should do when it is unsure, and make that behaviour stopping rather than guessing.
If you are choosing what to build in the first place, the Agent Idea Filter includes the risk questions, and the 7-Part Job Description is where the scope and the escalation rules get written down in a form the agent can follow. If you are earlier than that, the roadmap for beginners covers the sequence, and the ethics of autonomy is one of the modules in DSP AI Agent Mastery rather than an afterthought — because the people building these systems are the ones who decide how they behave.
Ready to build AI agents yourself?
DSP AI Agent Mastery — self-paced, 16 modules, starts from zero.
Start AI Agent Mastery →